import numpy as np
import matplotlib.pyplot as plt
from IPython.display import Markdown

plt.rcParams["font.family"] = "Noto Sans CJK JP"

T, R = 1000, 1000  # 1試合の回数,試合数
G, C, P = 0, 1, 2  # グー,チョキ,パー(a は (a+1)%3 に勝つ)
PAYOFF = np.array([0, 1, -1])  # (h - a) % 3 -> a から見た利得


def payoff(a, h):
    return PAYOFF[(h - a) % 3]


class EpsGreedy:
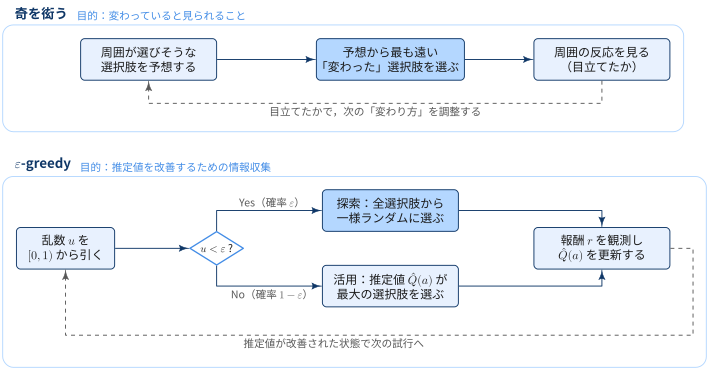
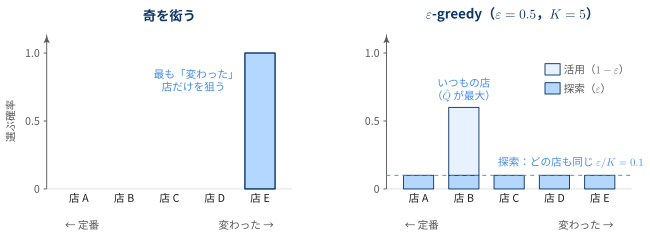
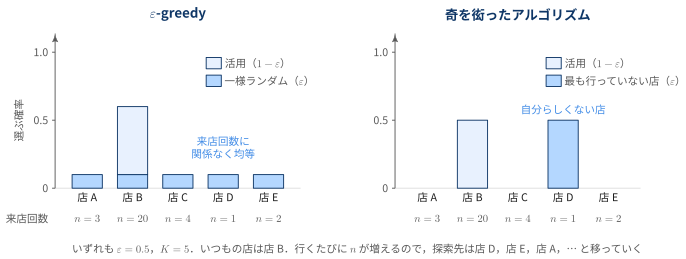
    """kiwo=False なら ε-greedy,kiwo=True なら奇を衒ったアルゴリズム"""

    def __init__(self, eps=0.1, kiwo=False):
        self.eps, self.kiwo = eps, kiwo

    def reset(self, rng):
        self.rng = rng
        self.Q = np.zeros((R, 3))
        self.n = np.zeros((R, 3))  # 自分がその手を出した回数

    def act(self):
        # 同点は乱数でくずす
        greedy = np.argmax(self.Q + 1e-9 * self.rng.random((R, 3)), axis=1)
        explore = self.rng.random(R) < self.eps
        if self.kiwo:
            # 自分がこれまで最も出していない手(自分らしくない手)
            alt = np.argmin(self.n + 1e-9 * self.rng.random((R, 3)), axis=1)
        else:
            alt = self.rng.integers(3, size=R)
        self.explore = explore  # 探索した回かどうか(対戦3の集計用)
        return np.where(explore, alt, greedy)

    def update(self, a, h):
        r = np.arange(R)
        self.n[r, a] += 1
        self.Q[r, a] += (payoff(a, h) - self.Q[r, a]) / self.n[r, a]


class Thompson:
    def reset(self, rng):
        self.rng = rng
        self.cnt = np.ones((R, 3, 3))  # [試合, 自分の手, 勝ち/あいこ/負け]

    def act(self):
        g = self.rng.gamma(self.cnt)
        p = g / g.sum(axis=2, keepdims=True)
        return np.argmax(p[:, :, 0] - p[:, :, 2], axis=1)

    def update(self, a, h):
        outcome = np.array([1, 0, 2])[(h - a) % 3]  # あいこ→1, 勝ち→0, 負け→2
        self.cnt[np.arange(R), a, outcome] += 1


class Hedge:
    def __init__(self, eta=0.1):
        self.eta = eta

    def reset(self, rng):
        self.rng = rng
        self.S = np.zeros((R, 3))  # score[a]:毎回 a を出していたときの累積利得

    def act(self):
        w = np.exp(self.eta * (self.S - self.S.max(axis=1, keepdims=True)))
        cdf = np.cumsum(w / w.sum(axis=1, keepdims=True), axis=1)
        return (self.rng.random((R, 1)) > cdf).sum(axis=1).clip(max=2)

    def update(self, a, h):
        self.S += payoff(np.arange(3)[None, :], h[:, None])


class Fixed:
    def __init__(self, p):
        self.p = np.asarray(p, dtype=float)

    def reset(self, rng):
        self.rng = rng

    def act(self):
        return self.rng.choice(3, size=R, p=self.p)

    def update(self, a, h):
        pass


def play(A, B, seed):
    """R 試合を並列に行い,A から見た利得と両者の手を返す"""
    rng = np.random.default_rng(seed)
    A.reset(rng)
    B.reset(rng)
    u = np.zeros((R, T))
    ha = np.zeros((R, T), dtype=int)
    hb = np.zeros((R, T), dtype=int)
    for t in range(T):
        a, b = A.act(), B.act()
        u[:, t] = payoff(a, b)
        ha[:, t], hb[:, t] = a, b
        A.update(a, b)
        B.update(b, a)
    return u, ha, hb


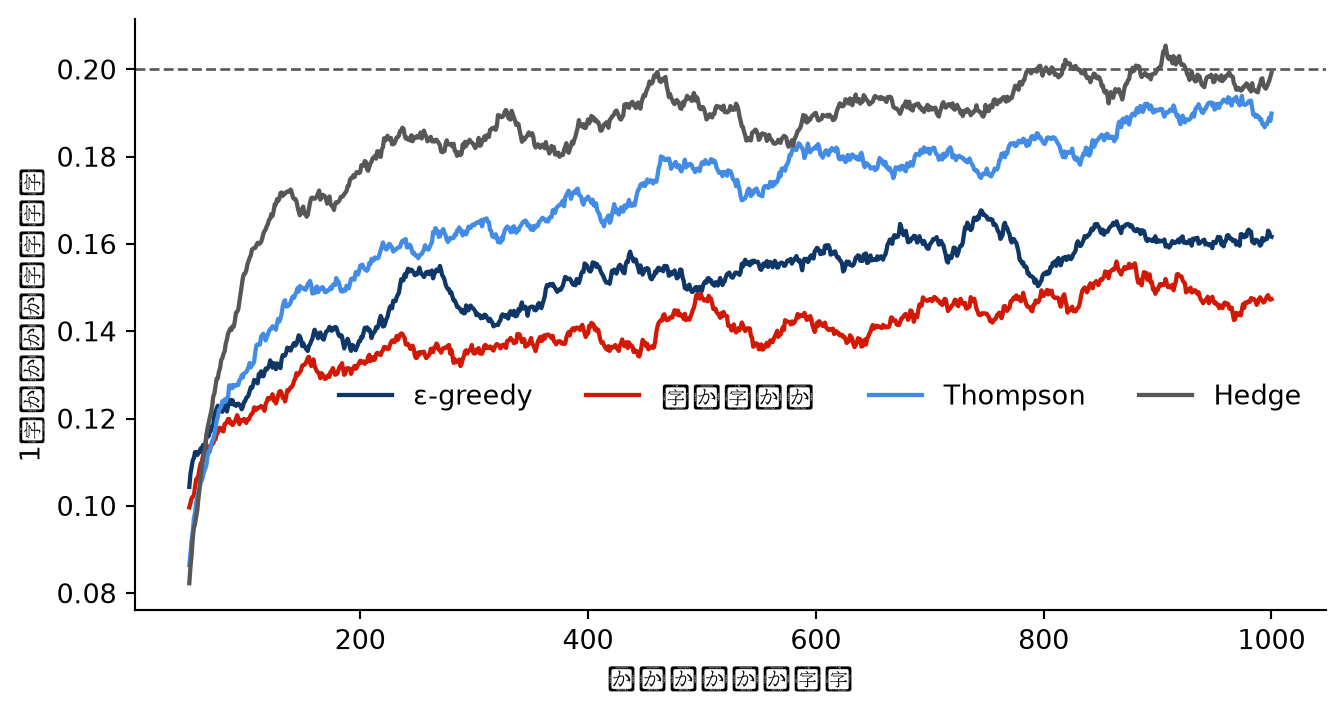
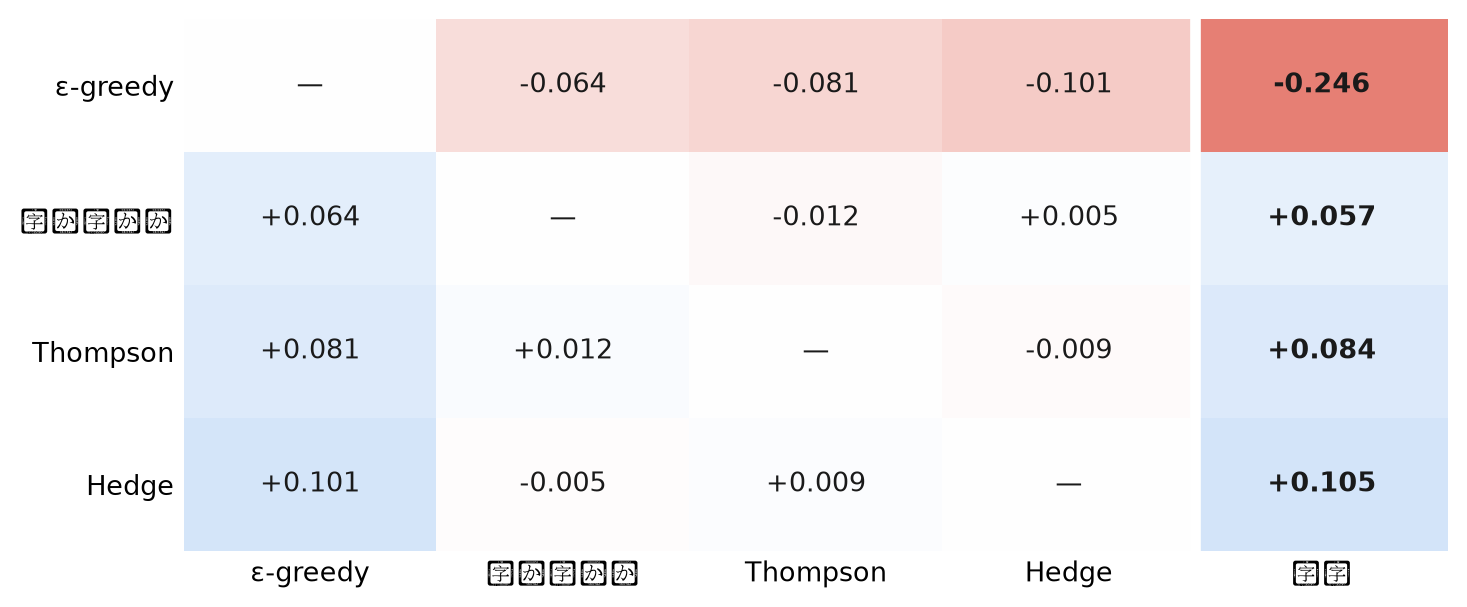
algos = {
    "ε-greedy": lambda: EpsGreedy(0.1),
    "奇を衒った": lambda: EpsGreedy(0.1, kiwo=True),
    "Thompson": lambda: Thompson(),
    "Hedge": lambda: Hedge(0.1),
}
names = list(algos)
colors = {"ε-greedy": "#0E3666", "奇を衒った": "#D31804",
          "Thompson": "#428CE6", "Hedge": "#575757"}